This quantum leap could be just the breakthrough Firefox needed to set event coordinates during HTML 5 mouse drag events.
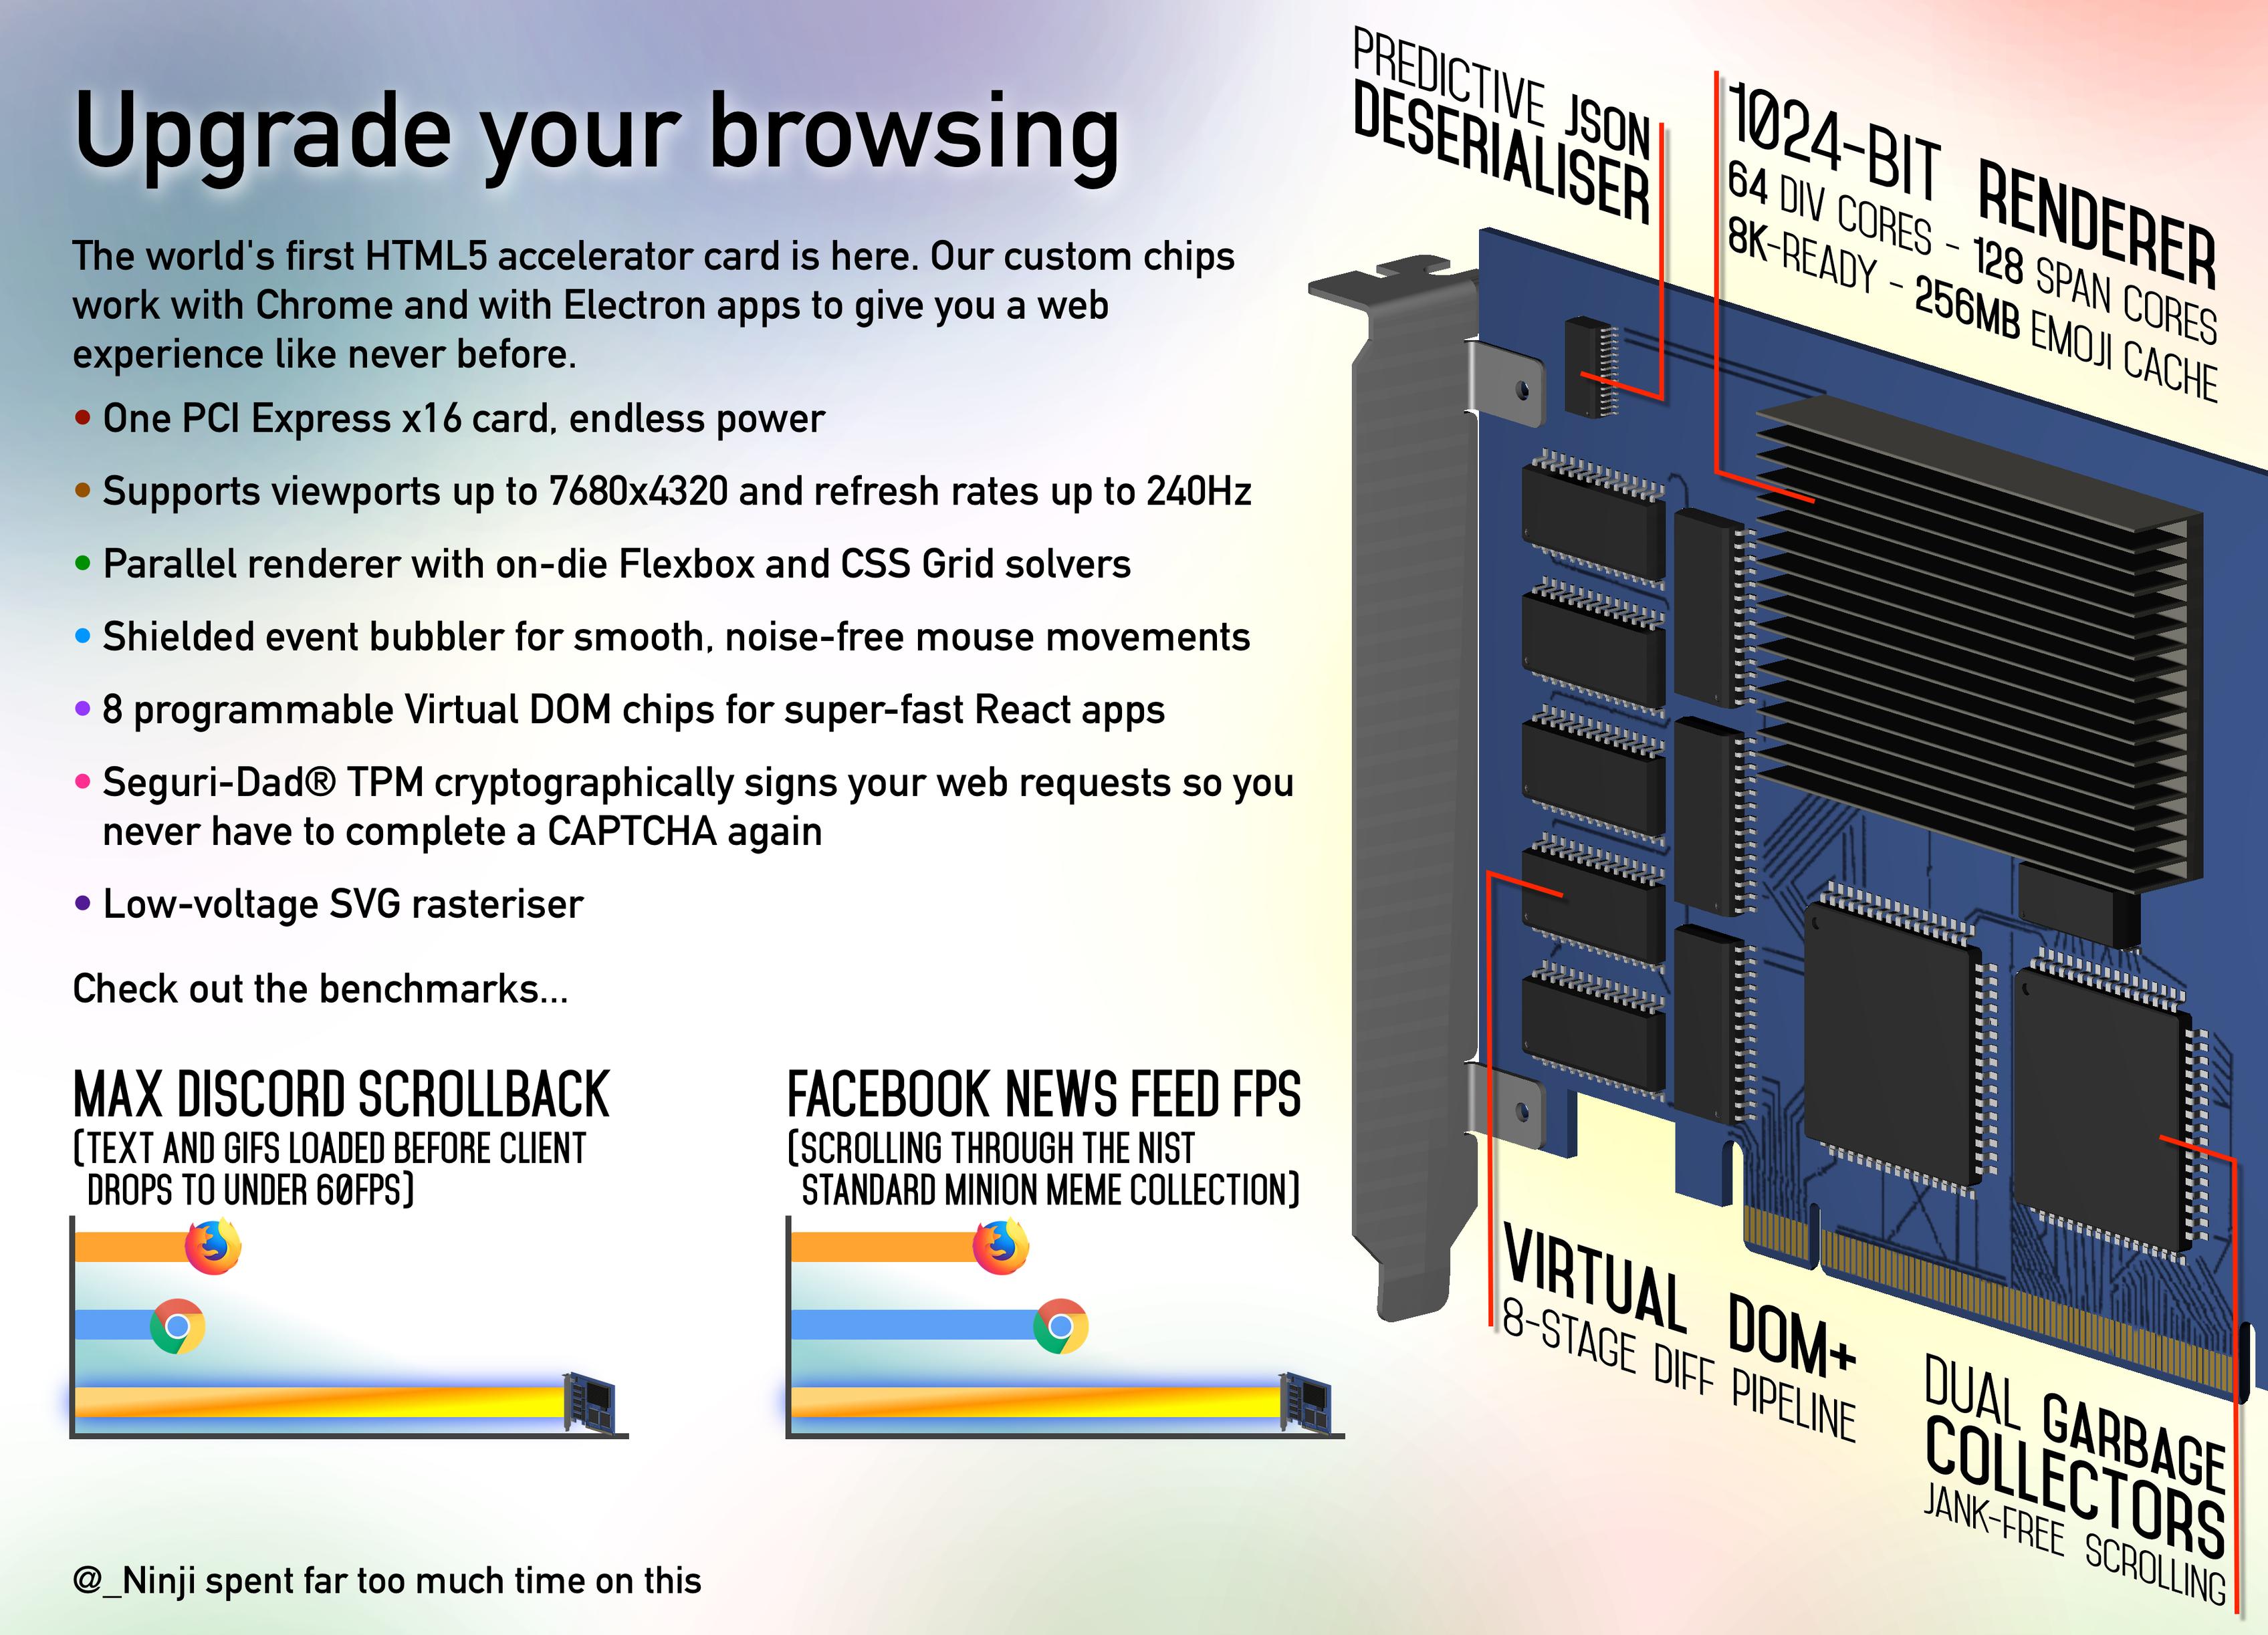
Ok but how bad does it get when the 256MB emoji cache is full? Cause that’s not enough space for all my emoji.
Needs 2x 10GbE ports to download bloated React apps directly into its onboard cache. Otherwise perfect.
As someone who loves expansion slots and hates how GPUs keep taking them away, I’d legit want one of these if they were real. Hell, I’m still mourning the death of the physics card.
Imaging putting a “grep card” into your computer and suddenly grep is ten times faster
regex accelerator, with direct communication to your disk drives!
cargo install ripgrep
PhysX?
Oh man, the only time I have ever seen a PhysX card mentioned in the wild was back then on my fathers XP machine in Crazy Machines 2. And I wanted that sucker so badly. Never laid my hands on one though. Now that I’m thinking about it, I don’t even know what they look like…
Removed by mod
I wish I didn’t know developers who would look at this and go “What’s the joke? Sounds like a good idea.”
It does sound like a good idea tbh
Guilty.
95 percent of the people using computers are just using them for a browser.
Let’s implement the DOM in hardware!
Let’s implement a web without DOM-abused-as-GUI.
Wait… what?
Nothing quite like locking yourself further into a broken, patched together frankenmess forever based only on momentum.
Hey!
Seems to be working for the current generation of AI primitives used…
I just learned about WebXR so yesterday I set up a new Angular project to build a VR game in (it’s Angular because I couldn’t figure out how to use the a-frame libraries custom html tags in React/JSX).
Using Javascript for calculating how 3d objects interact doesn’t feel too bad, but there is something uniquely cursed about defining those objects in plain ol HTML.
Damn do you need 64gb of sweet DDR5 to run this
No, it requires at least 256 GB of unified memory to run its AI.
I love the idea that somebody at NIST is in charge of collating a Standard Minions Meme Collection.
You know it would be some suburban moms.
This is brilliant.
It’s gonna need lots of RAM and then cost a fortune…
Don’t worry we offer financing options at very fair rates which also include a discount for the first year of the mandatory ad-supported subscription required to use the card.
I want that thing to never do a captcha again, please
The day is getting close, as long as the site uses rePrompt and you sign in to Google, on a Google browser, on a Google certified Android device with proprietary Google services. Otherwise maximum intruptions for you.
With catptchas becoming more and more common as sites try to stop AI crawlers, I suspect that’s going to become a real thing…
A real thing that irrevocably identifies you online, with absolutely no anonymity, and costs $9.95 per month, and only works on Cloudfare captchas.
I think the only valid use of Ai should be to solve captchas for you.
Actually an iPhone is a bit more than $9.95 a month https://support.apple.com/en-gb/guide/iphone/iph4f43a30c9/ios
I know this is a joke - but there totally is hardware acceleration for some of this stuff in modern processors. There definitely is for JS, JSON and generally string stuff. It’s not even x86 only, ARM got these kinds of things as well (although likely less of it)
Hardware acceleration for an interpreted programming language? Can you point me to a specific example or clarify what you mean, because I find that hard to believe.
Tbf, it’s not really like processors have ‘DO JS STUFF’ instructions, they are not made for one language or data format specifically of course. But ultimately, instructions are shaped by things people use.
JSON for example requires searching strings for structural characters:
,,{,}etc. Iirc you can use VPSHUFB (‘Packed Shuffle Bytes’ or so, AVX >=2) to map 32 bytes (or 64 on AVX-512 I guess) to any structural character in one instruction. That’s quite the speedup compared to comparing all of them to all special characters one at a time, even considering SIMD kinda moves on its own pace. And it’s exactly the kind of stuff you would use in your JS engine to make parsing JSON crazy fast, even when it’s plain text, which is obviously less than ideal for a computer.I remember there was some instruction that was introduced specifically because of something JS does all the time tought. I forgot what it was, maybe someone else can help out.
js isn’t really interpreted anymore, it’s all jit-compiled. instructions that help with common compiler operations are pretty standard.
but there have been cpu features for interactive languages for a long time. lispmachines and forth systems are the obvious ones, but there’s been a push towards software-specific cpu dev even in the mainstream. UltraSPARC could run java natively, and itanium was designed with object-oriented systems in mind.
I’ve been browsing with jit disabled for years now. No regrets.
I’m not sure what they were going for, but I know that modern browsers do just in time compilation for regularly repeated code parts to allow much faster execution, so “interpreted programming language” may be a little of a blurry definition. See https://developer.mozilla.org/en-US/docs/Glossary/Just_In_Time_Compilation
I couldn’t find any info on any hardware specific to JS/JSON for clients but I’m no expert, maybe they will provide more info.
I’ve always wondered about string handling - it’s so common, and seemed to be an afterthought in every processor I ever learned about their instructions. Of course, I last touched assembly language 30 years ago, so… I would hope there’s been some progress since then.
What’s amazing is that actually everything in there could be doable unironically.
But more amazing (and embarrasing) is the fact that we have reached to this point where optimization is that undervalued by most programmers. Horrible timeline to live in, when AI is messing up with hardware prices.
The 8088 CPU (the one from the original IBM PC) had special string scanning support with both instructions and registers. The SI (source index) and DI (destination index) were such registers, and a bunch of instructions related.
However, specialized instructions take die area on the CPU. In the 1980s a movement based on the observation that most sophisticated instructions were not used much, and it would be better to concentrate on making very common operations (like add, load, store, shift, or whatever) fast. That started reduced-instruction set computing (RISC).
RISC was so successful that x86 chips switched to the model with a RISC-like core and implementing more sophisticated fuctions in “microcode”. Today Linux can load microcode, which is basically patching the firmware of the CPU itself.
Anyway, of course the drive towards RISC ended as people realized that some advanced functionality is really useful. In the 1990s and 2000s this was focused around new limitations: it was impossible to get higher frequencies so running a single core couldn’t get faster. CPUs added SIMD (single instruction, multiple data) support as well as hyperthreading.
Now… revisiting string operations and adding CPU support would be possible. Engineers at CPU design shops look at how their chip space is used and optimize the die area for instruction sets and also registers, cache, and so on. But my guess is that it doesn’t make sense or it would have happened a decade ago already.
RISC was so successful
I would say popular rather than successful, but yeah, I was “actively” in the assembly code around then.
Around 2010 I was working with NIOS cores on FPGAs, which were ultra-flexible (sort of the ultimate microcode embodiment), but not really efficient or performant the way a fixed ARM core is. At the time Xilinx was promising ARM cores on-chip beside the FPGAs “real soon” - it took a while, but they finally delivered and that is a nice arrangement when you need specialized processing, which most projects I have seen implemented with those ARM+FPGA uZed and similar boards don’t really need and they can better be implemented on a simple ARM core system, maybe with a few built-in timer-latches, instead.
In the 2007 timeframe we were looking to squeeze performance out of an algorithm to bring an analysis time down from hours to 5 minutes or less, massive parallelism was on the table but expensive - not unaffordable in the application - but unwieldy in the space / bandwidth taken by the hardware. SIMD, MIMD - the compiler optimizers seemed to be doing well enough with those to get what was possible, but we were still over 2 hours. Finally, a code review of the profiler identified bottleneck turned up a queer looking nested loop structure that was causing cache misses on the inner loop. We restructured that and sped things up 100x, 5 minute execution on a laptop, more like 2 minutes on the quad-core workstation target. I think the “chief scientist” was disappointed that we wouldn’t be building an array of 100 workstations to crunch the numbers in parallel. RAM is fast, cache is faster.
I’m sure they’ve run the numbers and strings are better in code than hardware overall - I just constantly instantiate and manipulate string objects and wonder how much that adds up throughout the app execution. I’m going to guess that most string operations are small enough to fit in cache these days, and that’s all the help they need.